
AI ROI: Why the Published Numbers Disagree — and How to Measure Your Own
Between April and June 2025, Google Cloud surveyed 3,466 senior business leaders at enterprises above $10 million in revenue and reported that 74% were achieving ROI on generative AI within the first year. In the same period, MIT’s Project NANDA reviewed more than 300 AI initiatives and concluded that 95% of organisations were getting no measurable return at all.
Both numbers are real. Both come from serious research. They describe the same market in the same months and they are almost perfectly opposed.
If you are building a business case, this is not an academic problem. Whichever figure your board has read is now the benchmark you are being measured against, and neither one tells you anything about your own initiative. This article explains why the published AI ROI numbers contradict each other, what that means for your business case, and how to calculate a number that survives scrutiny from your own finance team.
Why AI ROI figures contradict each other
Four differences explain almost all of the gap between published AI ROI findings.
Who asked, and who paid. Google Cloud’s report was commissioned by a company that sells AI infrastructure and conducted with National Research Group; the accompanying analysis was published by its VP of Global Generative AI go-to-market. MIT’s study was academic. That does not make the vendor research dishonest — the sample is large and the methodology is stated — but a vendor-commissioned survey and an independent P&L review are answering the questions their sponsors care about, and those questions differ.
Self-report versus measurement. Google Cloud asked executives whether they were seeing ROI. MIT looked for measurable profit and loss impact. An executive who believes a tool is working and an accountant who can find the saving in the ledger are answering different questions, and the gap between them is where most of the 74-versus-95 discrepancy lives.
It is worth seeing what self-report looks like at the edges. The same Google Cloud research reports a 70% reduction in breach risk and 50% faster mean time to respond in security operations. Both are executive assessments rather than audited measurements, and breach risk in particular is not a quantity most organisations can observe directly — you cannot count the incidents that did not happen. The figure may well reflect something real. It is simply not the same kind of number as a cancelled contract.
Who was in the sample. Google Cloud surveyed organisations that had already deployed generative AI, at enterprises above $10 million in revenue. The 74% is a share of that population — companies already far enough along to have something in production. Everyone whose programme died before deployment is excluded, which is precisely the group MIT was counting. Survivorship explains a large share of any optimistic AI ROI figure.
What counts as a return, and by when. MIT assessed at roughly six months. S&P Global’s 2026 research used a twelve-month horizon and found 37% of initiatives launched in the previous year live and delivering value, with a further 46% on track. Google Cloud’s “within the first year” is a third window again. Move the date and the number moves with it.
The practical conclusion: published AI ROI rates are not benchmarks. They are measurements of different populations, by different methods, against different definitions. Quoting one in your business case invites the obvious question of why you did not quote another.
What the research does tell you
Strip out the headline percentages and the studies agree on something more useful: where returns actually came from.
MIT’s findings were specific. The documented wins were in the back office — elimination of business process outsourcing worth $2–10 million annually in customer service and document processing, a 30% reduction in external creative and content spend, roughly $1 million a year saved on outsourced risk checks at a financial services firm. Front-office gains were real but smaller: about 40% faster lead qualification, a 10% improvement in customer retention.
Critically, the gains came without material workforce reduction. Teams got faster; headcount and structure stayed the same. The value appeared as reduced external spend — cancelled contracts, lower agency fees, work brought back in-house from expensive suppliers.
Google Cloud’s data, from the optimistic end of the range, points the same way on structure even while disagreeing on magnitude: 70% of leaders reported productivity gains, 63% customer experience improvements, 56% business growth, with most of that last group estimating a 6–10% revenue effect. Where its examples are concrete they are also the most credible — 120 seconds saved per customer contact is the kind of figure an operations team can verify.
And one finding appears in both studies, which makes it the most reliable thing in the literature: executive sponsorship separates the groups. Google Cloud found 78% of organisations with comprehensive C-suite sponsorship reported ROI on at least one generative AI use case, against 43% without. MIT reached a compatible conclusion from the other direction, finding that the successful minority combined domain-level ownership with executive accountability.
Why this matters more in 2026 than it did in 2024
The question has moved from whether to spend on AI to whether the spending can be justified.
Gartner forecasts worldwide AI spending of $2.59 trillion in 2026, a 47% year-on-year increase — but notes that the spending so far has been driven by technology vendors and hyperscalers rather than by enterprises. Its analyst John-David Lovelock is direct about what is holding the enterprise side back: organisations currently show limited appetite for using AI to drive disruptive change, favouring tactical initiatives with incremental gains in efficiency and productivity, and CIOs face real difficulty proving the value of AI investments and demonstrating tangible business outcomes.
Bain put the same finding more bluntly after surveying companies on the cost reductions AI actually delivered against what they had predicted: “The technology worked. The value didn’t arrive.”
That is a market-wide version of the problem this article addresses. The budget exists. What is missing is the arithmetic that justifies it.
Start with a baseline, or you will never prove anything
This is the step most often skipped, and skipping it is why so many initiatives cannot demonstrate a return even when they produced one.
If you do not know what the process cost before the system went in, no amount of post-launch measurement will produce a defensible number. You will be left arguing from impressions, which is precisely the position that produces a 74% self-reported success rate and a 95% measured failure rate from the same market.
A usable baseline needs four things, all captured before any build starts:
- Volume. How many cases, documents, tickets, or transactions per month, with seasonality if it exists.
- Unit cost. Fully loaded, including the people, the tools, and the outsourced portion.
- Quality rate. Error, rework, escalation, or reopen rate. If it is not currently tracked, track it for a month. That month is the cheapest work in the entire project.
- Cycle time. How long the process takes today, measured rather than estimated.
Two weeks of baseline measurement is a rounding error against a build budget and it is the difference between a business case and an anecdote.
On attribution. AI initiatives rarely land in isolation. A support automation goes in during the same quarter as a headcount change, a new product launch, and a process redesign. If you cannot isolate the effect, say so in the business case rather than claiming the whole delta. The credible options are a control group where one is available — one region or team unchanged for a period — or a stated share of the effect with reasoning. Finance teams accept a defensible partial attribution far more readily than an implausible complete one.
How to build an AI ROI calculation that survives scrutiny
A defensible AI ROI number has three properties: every input traces to something your finance team already reports, the cost side is complete, and the measurement window is agreed before work starts.
The benefit side
Four categories, in descending order of how easy they are to defend:
Eliminated external spend. Contracts you can cancel or reduce: BPO, agency retainers, outsourced review or processing, per-seat tools the system replaces. This is the strongest category because the saving appears in the ledger as a line that used to exist and now does not. It is also where MIT found most of the real returns.
Reduced rework and error cost. Cases reopened, documents corrected, transactions reversed, compliance findings. Defensible when the current rate is already tracked — which is what the baseline is for.
Reallocated time. Hours saved multiplied by loaded cost. The most commonly used and the weakest, because saved hours only become money if the time is actually redeployed to something that earns or if headcount genuinely changes. Finance teams know this. Present it as capacity rather than as savings unless you can point to what the capacity was used for.
Revenue effects. Faster response, better conversion, higher retention. Real but hardest to attribute. Use it to support a case, not to carry one.
The cost side, including what gets missed
Build cost is the part everyone estimates. The rest is where business cases come apart.
- Discovery and architecture — defining scope, selecting models, designing data flows. Small in absolute terms and routinely omitted entirely
- Build — engineering, design, project management
- Integration — connecting to the systems where work actually happens, usually underestimated by more than the model work
- Data preparation — the work to make data usable, which for many initiatives exceeds the build
- Licences and inference — the line most likely to break your forecast. See below
- Change management and training — the line most often set to zero, and the one that determines whether anything gets used
- Ongoing maintenance, monitoring, and retraining — models drift, sources change, integrations break
- Security and compliance review — S&P Global’s 2026 data ranks cybersecurity as the most acute skills shortage affecting AI initiatives, ahead of AI development itself. Review capacity is a real cost and a real delay
How often does this go wrong? The FinOps Foundation’s State of FinOps 2026, drawn from 1,192 practitioners collectively responsible for more than $83 billion in annual cloud spend, found that 73% of organisations reported AI costs exceeding their original projections. The share of FinOps teams managing AI spend went from 31% in 2024 to 63% in 2025 to 98% in 2026, and the Foundation locates 80–90% of AI expenditure in inference rather than training.
For sizing your own programme, spend data is more useful than forecasts. Ramp reports that among businesses spending on AI, the median company now dedicates roughly 15% of its software budget to AI tools — a share that barely existed two years ago — and suggests budget planning assume 50–100% annual growth in AI spend for most companies.
The inference line, and why it breaks forecasts
Consumption pricing behaves unlike anything else in a software budget, and 2026 produced the clearest demonstration of it available.
Uber rolled out agentic coding tools across its engineering organisation in December 2025. Adoption climbed from 32% to 84% of roughly 5,000 engineers by March 2026. By April, the entire 2026 AI budget was gone — four months into the year. Average monthly cost landed at $150–250 per engineer, with power users running $500–2,000. The chief technology officer confirmed the overrun and said the company was back to the drawing board on its assumptions. A per-engineer monthly cap with an exception process followed.
Three details matter more than the headline. First, the deployment succeeded on every measure it was designed against — around 70% of committed code was AI-generated, with 11% of backend updates written by fully autonomous agents. This was not a failed rollout. Second, Uber’s R&D spend was $3.4 billion in 2025; this was a forecasting failure, not an affordability one. Third, and most relevant to anyone writing a business case, Uber’s chief operating officer said publicly that increased token consumption was not translating into proportionally more shipped features: “That link is not there yet.” That is an attribution problem, stated by an operator rather than a researcher.
The underlying dynamic is structural. Bain reported in June 2026 that token costs halved between December 2024 and December 2025 while tokens consumed grew by 450% over the same period, as companies upgraded models rather than pocketing the savings and as agents consumed more tokens per query. Their summary of the pattern: “The models get cheaper. The usage gets heavier. The bill stays stubbornly high.”
Bain projects an operating expense mix settling at roughly 70% human headcount and 30% tokens, and frames the shift as structural rather than a budgeting problem — which means the fix is not a bigger number in the forecast but a different way of forecasting.
The practical consequence for a business case: model inference at expected production volume, not at pilot volume, and add a governance line for caps and monitoring. A pilot’s run cost tells you almost nothing about production’s.
The window
Agree it before work starts. MIT’s assessment ran to roughly six months, S&P’s to twelve, Google Cloud’s to a year. None is correct in the abstract, and inheriting one because it appeared in a report you read is how business cases end up judged against a standard nobody chose.
Set the window, name what result would count as failure, and name the person who calls it.
A worked calculation
The figures below are illustrative — round numbers chosen to show the method, not drawn from a specific engagement. The structure is what matters.
The scenario. A back-office document review process. 8,000 documents a month. Twelve minutes average handling time. Fully loaded cost of $45 an hour, so $9 a document. Thirty per cent of the volume is sent to an outsourcing provider at $11 a document. The target is automated first-pass review on 55% of volume, with a person confirming each result.
Baseline, captured before any build
| Measure | Value |
|---|---|
| Monthly volume | 8,000 documents |
| Internal handling cost | $9 per document |
| Outsourced volume | 2,400 documents per month |
| Outsourced cost | $11 per document, $26,400 per month |
| Rework rate | 6% |
| Cycle time | 3.5 days average |
The cost side
| One-off | Amount |
|---|---|
| Discovery and architecture | $18,000 |
| Build and integration | $95,000 |
| Data preparation | $40,000 |
| Change management and training | $15,000 |
| Total one-off | $168,000 |
| Running, per month | Amount |
|---|---|
| Inference at production volume | $2,640 |
| Monitoring and maintenance | $3,060 |
| Total monthly | $5,700 |
Note the inference line. At pilot volume of 800 documents a month it would have been around $480. Modelling the production figure from the pilot understates it by more than five times — the same class of error that cost Uber its annual budget in four months, at a different scale, and the reason 73% of organisations overshoot their AI cost projections.
The benefit side
| Category | Annual value | Defensibility |
|---|---|---|
| Eliminated external spend — outsourcing contract ends | $316,800 | Strong. A ledger line that existed and now does not |
| Reduced rework — 6% to 3.5% on automated volume | Include only if the 6% was tracked before the build | Moderate |
| Reallocated time — 880 hours a month | $475,200 if counted as cash | Weak. Shown separately, not added |
| Revenue effects — faster cycle time | Supports the case, does not carry it | Weak |
The result
| Defensible version | Version counting reallocated time as savings | |
|---|---|---|
| Annual gross benefit | $316,800 | $792,000 |
| Annual running cost | $68,400 | $68,400 |
| Annual net | $248,400 | $723,600 |
| Payback on $168,000 | 8.1 months | 2.8 months |
The second column is how most AI business cases are written. It is not fraudulent — those 880 hours are genuinely freed — but 880 hours a month is more than five full-time equivalents of capacity, and unless those roles change or the capacity is visibly redeployed to something that earns, none of it appears in the accounts. A finance team will find that out, and the credibility cost lands on the next business case rather than this one.
Present both columns. Lead with the first.
Not sure your inputs are solid?
Two shapes of AI investment
Cost and return profiles differ enormously depending on whether you are replacing a system or adding a capability. Two CodeIT engagements illustrate the difference.
Replacing a system: the returns are visible, the cost is large
A global consumer goods company ran client and vendor support on a custom-built legacy system that required continuous maintenance, could not scale with request volume, and had no automation — so routine cases were handled manually across multiple markets.
CodeIT assessed the existing infrastructure, mapped case volumes and request types, and replaced the legacy system with Microsoft Dynamics 365 Customer Service and Copilot Studio, with AI agents handling routine inquiries and voice channels unified across regions. A team of four delivered it.
The results: 50–65% of support cases automated, response times 25–35% faster, and support costs down 20–30%.
Read that through the framework above. The support cost reduction is the defensible number — it is a line finance already reports, and it moved. The automation rate is the mechanism, not the return. The response time improvement is a customer experience effect that supports the case without carrying it. And the maintenance the old system required disappears from the cost side, a saving that never shows up in a benefits calculation unless someone remembers to look for it.
Adding a capability: the cost is small, the return is harder to isolate
A US company managing hybrid work needed to automate daily operations that were consuming staff time — desk booking, finding when colleagues would be in a given office, arranging schedules around them.
CodeIT embedded two specialists, a business analyst and a data scientist, into the client’s on-site team. The work ran in four stages: product discovery to define functionality and user stories; architecture, including a formal evaluation of fine-tuned language models with a written report that stakeholders reviewed and approved before selection; development of the assistant as a standalone microservice in Python with LangChain; and integration into Slack and Microsoft Teams via API. The MVP shipped with five use cases. The partnership has been running since 2022.
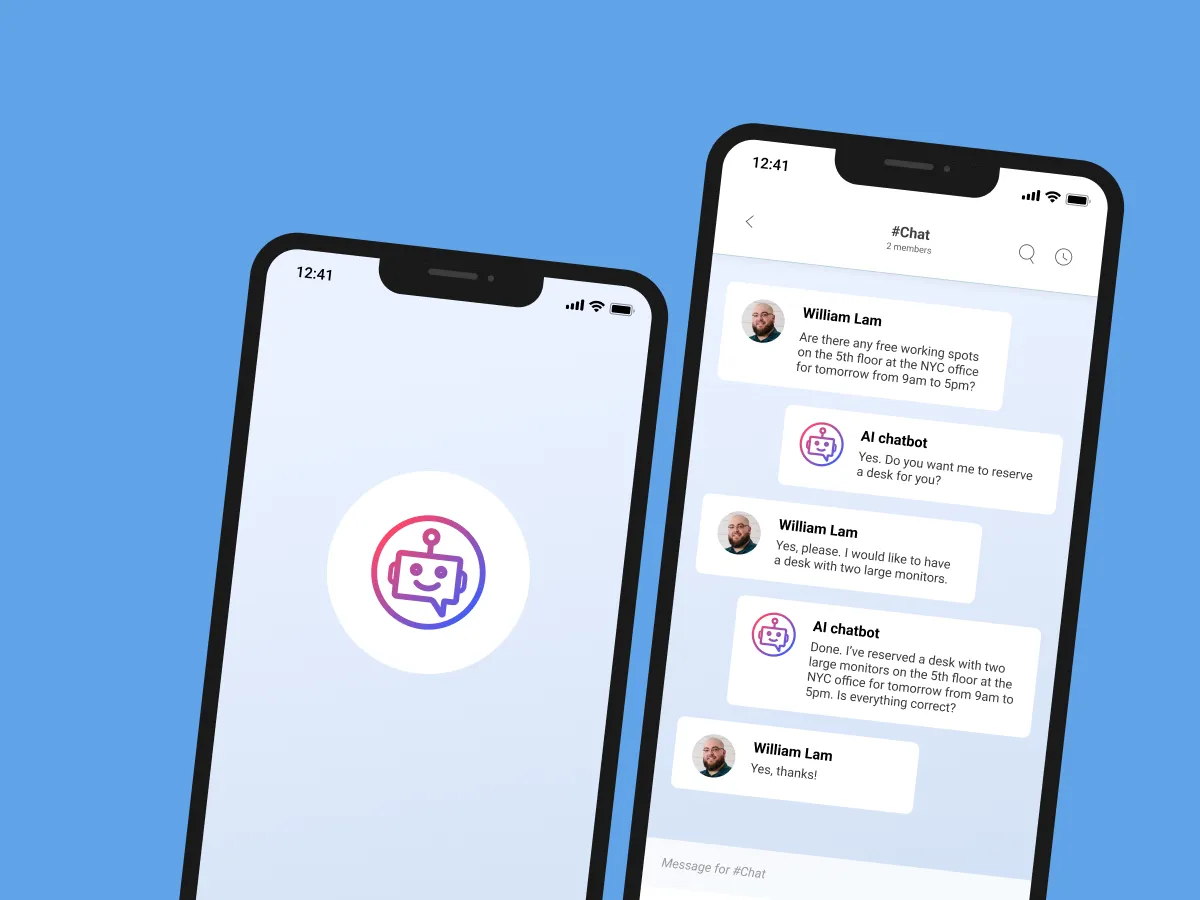
This shape is instructive precisely because of what it shows on the cost side. A two-person team over an MVP scope is a materially different investment from a four-person platform replacement — but the cost line items are the same ones the list above enumerates, and two of them are the ones most often left out of estimates entirely. Discovery and architecture were formal stages with deliverables, not overhead absorbed into the build. Model selection was a research task producing a document that stakeholders signed off, not a default choice made by whoever set up the account.
Both are real costs. Neither appears in an estimate that starts at “how long will the engineering take.”
The return side is harder here, and worth being honest about. Time recovered from booking a desk or locating a colleague is genuine, but it is reallocated time — the weakest of the four benefit categories, and the one the worked calculation above shows in its own column for a reason. It is also spread thinly across many people rather than concentrated in a measurable process. A capability-addition project of this shape needs its baseline defined more carefully than a system replacement does, because there is no external contract disappearing from the ledger to point at.
What to do when the number is not good enough
Most ROI work assumes the answer will be positive. Frequently it is not, and a business case that fails honestly at week three is worth considerably more than one that succeeds dishonestly and fails at month fourteen.
Three responses are usually available before abandoning an initiative:
Change the use case, not the model. MIT found roughly half of generative AI budget going to sales and marketing while the sharper returns appeared in back-office automation — largely because sales metrics are easier to attribute, not because the value is greater. If the numbers do not work on a customer-facing use case, the same capability applied to a back-office process often looks different.
Change the sourcing. Build cost dominates many weak business cases. MIT found external partnerships reached deployment about 67% of the time against roughly 33% for internal builds, while cautioning that the difference may reflect organisational capability rather than the approach itself. Where a mature product exists, configuring it is frequently the difference between a case that works and one that does not.
Reduce the question. If the full initiative does not clear the bar, a scoped proof of concept can answer the expensive uncertainty for a fraction of the cost. A proof of concept exists to make the unknowns cheap rather than to demonstrate that something is possible.
If none of the three changes the answer, the honest outcome is to stop — and stopping at week three, with a documented reason, is a good result rather than a failure.
Organisations that want an outside view on the assumptions, particularly when internal estimates diverge widely, often bring in AI advisory services for the business case rather than the whole programme.
Get a business case your CFO will accept
FAQ
There is no reliable published benchmark, because the major studies measure different populations by different methods. Google Cloud’s 2025 survey of 3,466 executives at enterprises already using generative AI found 74% reporting ROI within a year. MIT’s 2025 review found 95% of organisations getting no measurable P&L return. S&P Global’s 2026 research found 37% of initiatives live and delivering value with 46% on track within twelve months. Calculate your own case from your own numbers rather than benchmarking against any of these.
Four reasons: who commissioned the research, whether returns were self-reported or measured in the ledger, whether the sample included failed initiatives or only deployed ones, and what measurement window was used. Vendor-commissioned executive surveys of organisations that already deployed successfully will always produce higher figures than independent P&L reviews of everyone who tried.
Capture a baseline first: volume, fully loaded unit cost, error or rework rate, and cycle time, measured before the build starts. Then build the benefit side from four categories in order of defensibility — eliminated external spend, reduced rework, reallocated time, and revenue effects. Build the cost side to include discovery, integration, data preparation, inference at production volume, change management, and ongoing maintenance, not just the build. Agree the measurement window and the failure threshold before work starts.
Eliminated external spend. A cancelled BPO contract or reduced agency retainer appears in the ledger as a line that used to exist and now does not, which requires no interpretation. MIT found this is also where most documented enterprise returns actually came from, with back-office BPO elimination worth $2–10 million annually in the cases they examined.
Present it separately from cash savings rather than adding it in. Freed hours are real, but they only become money if headcount changes or the capacity is visibly redeployed to something that earns. In the worked example above, counting reallocated time as savings shortens the apparent payback from 8.1 months to 2.8 — a difference a finance team will identify, at a cost to the credibility of the next business case.
Because consumption pricing does not behave like a licence. The FinOps Foundation’s 2026 survey of 1,192 practitioners found 73% of organisations exceeded their original AI cost projections. Uber exhausted its entire 2026 AI budget by April after agentic coding tools spread from 32% to 84% of its engineers in three months. Bain found token costs halved between December 2024 and December 2025 while consumption grew 450% — falling unit prices invite more usage rather than reducing spend. Model inference at production volume, and budget for caps and monitoring.
Use a control group where one exists — a region or team left unchanged for the measurement period — or state a share of the effect with the reasoning behind it. A defensible partial attribution is accepted far more readily by finance teams than an implausible claim to the entire delta.
It depends on the window you set, which is why you should set it explicitly. Published studies use six months, twelve months, and “within the first year,” and each produces a different success rate from broadly the same market. For a scoped back-office automation with a clear baseline, twelve months is a common and defensible horizon.
Test three changes before abandoning it: move the use case to a back-office process where returns are better documented, change the sourcing from internal build to configured product, or reduce the scope to a proof of concept that answers the expensive uncertainty cheaply. If none of them changes the answer, stopping early with a documented reason is the correct outcome.